Loading stories…
Latest
Every xSypher story, newest first — reporting, analysis, reviews and guides as they publish.
Yesterday
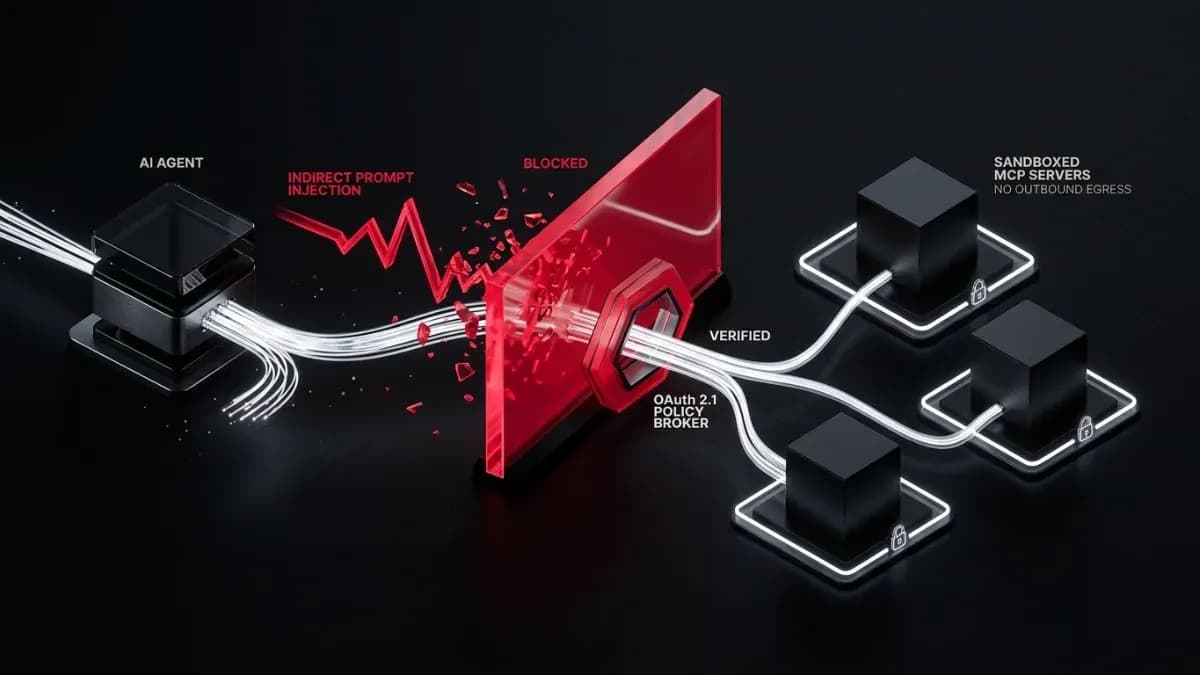
Cybersecurity / AI Security
How to Secure MCP Servers and AI Agents in Production
Tool poisoning, token passthrough, and unpinned npm installs break agents after launch. Follow this production hardening order to lock down MCP servers.
Anwar Iqbal Dawar · · 17 min read

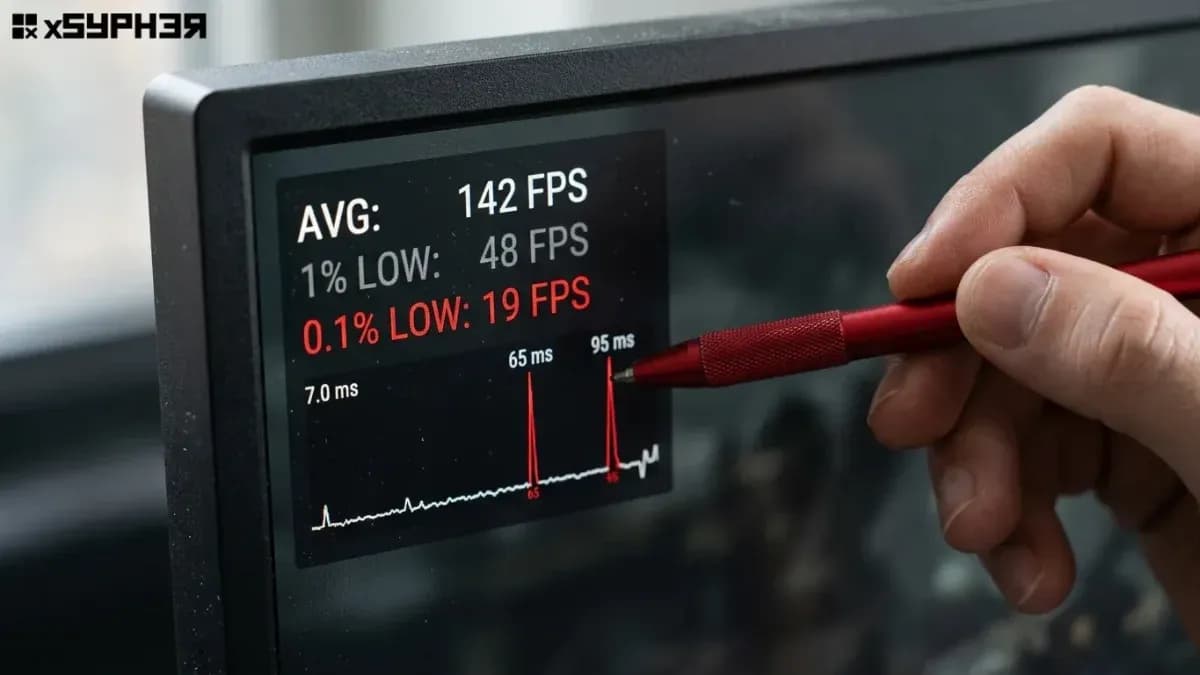
Gaming
Why High FPS Still Stutters: Frame Time, Shaders, and Sync
A 140 FPS average hides 100 ms frame-time spikes. Use PresentMon to isolate shader compilation, CPU limits, VRAM overflow, and VRR sync stutter.
Ameer Muawiya Khattak · · 13 min read

This week
Ai / Large Language Models
Why AI Hallucinates and How to Catch It Before It Costs You
Language models are trained to guess, not to say "I don't know." Here is why they fabricate citations and numbers, plus the validation workflow we use.
Anwar Iqbal Dawar · · 15 min read
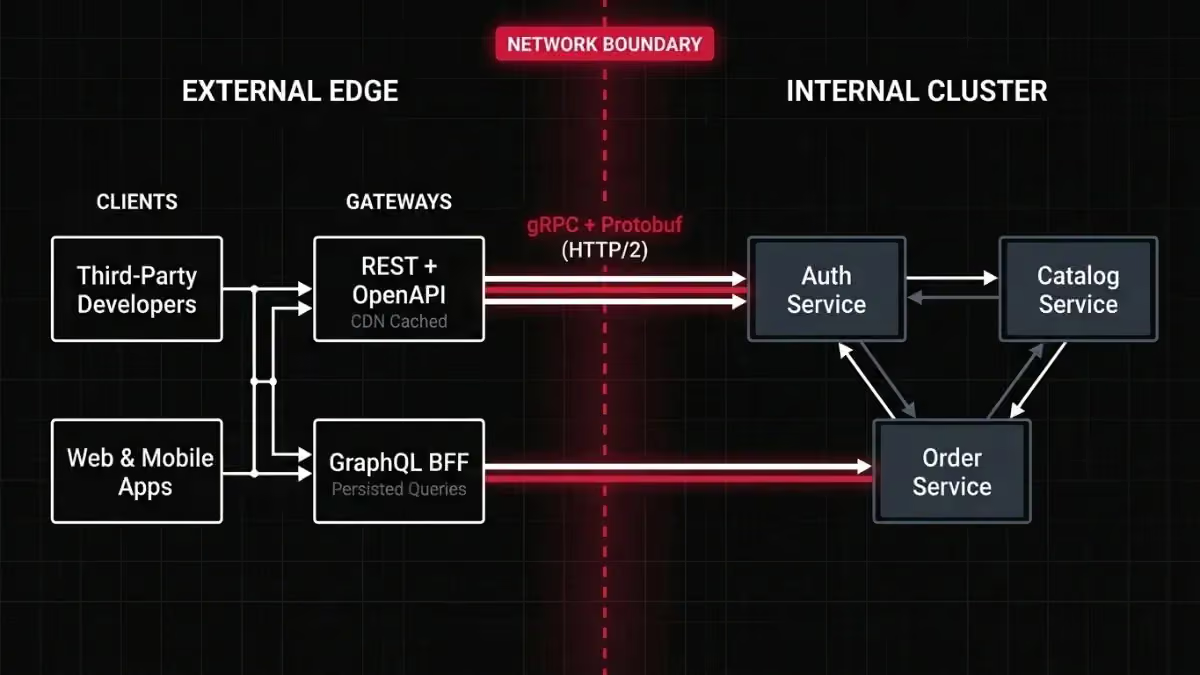
Programming / Backend Architecture
REST vs GraphQL vs gRPC: Choosing the Right API Architecture
Each style wins one axis and loses another. How caching, schema change, clients, operations and latency decide it, plus the hybrid most teams end up running.
Anwar Iqbal Dawar · · 15 min read
Gadgets / Laptops
How Much RAM Do You Actually Need in a Laptop?
What 8GB, 16GB, and 32GB really mean day to day — and why you may not be able to add more later.
Tariq Jameel · · 8 min read

Ai / AI Models
Local AI vs Cloud AI: Which One Fits Your Work?
When keeping models on your own hardware pays off, and when it quietly costs more
Anwar Iqbal Dawar · · 11 min read
Earlier
Software / Windows
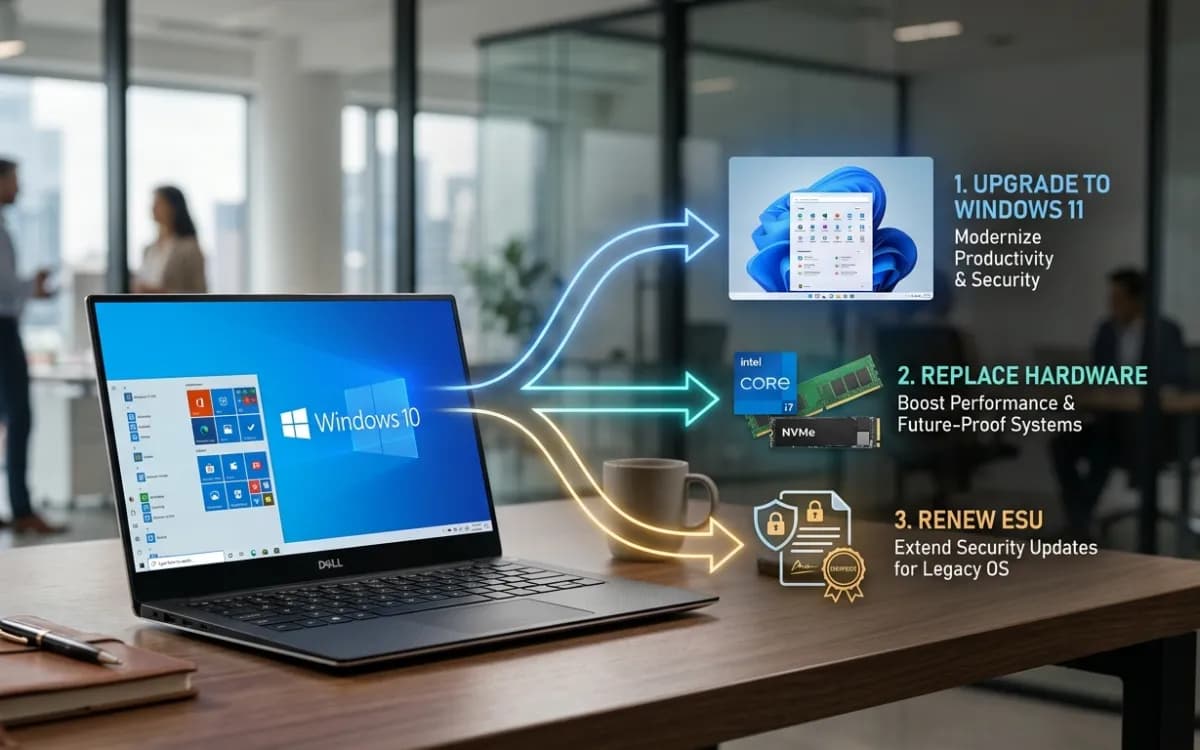
Windows 10 ESU Year 2: Pay, Upgrade or Replace
A per-seat decision model for mixed estates choosing between $122-per-device renewals, Windows 11 upgrades and hardware replacement.
Ameer Muawiya Khattak · · 14 min read
Cybersecurity / Product Security
CRA Article 14: Build a 24-Hour Exploited-Vulnerability Reporting Workflow
A PSIRT runbook that maps detection to the severity decision and the 24-hour, 72-hour and 14-day filings on ENISA's Single Reporting Platform.
Ameer Muawiya Khattak · · 19 min read
Cybersecurity / Endpoint security xSypher CyberOps · · 9 min read
EDR vs MDR: When Is 24/7 Security Worth Paying For?
A cheaper endpoint license won’t answer a 3 a.m. alert. Response authority, seat minimums and staff capacity change the buying decision.
xSypher CyberOps · · 9 min read
Ai / AI help-desk pricing
AI Support Agents for Small SaaS Teams: What a Resolution Costs
We priced Fin, Zendesk, Freshdesk and Help Scout at 300, 1,000 and 3,000 tickets a month. The billing meter you pick matters more than the sticker.
Anwar Iqbal Dawar · · 11 min read